Generate Images Directly from Human Speech
Department of Industrial Engineering and Operations Research
Indian Institute of Technology Bombay, Mumbai, India
Accepted at 35th ACM International Conference on Multimedia (ACM MM 2026)
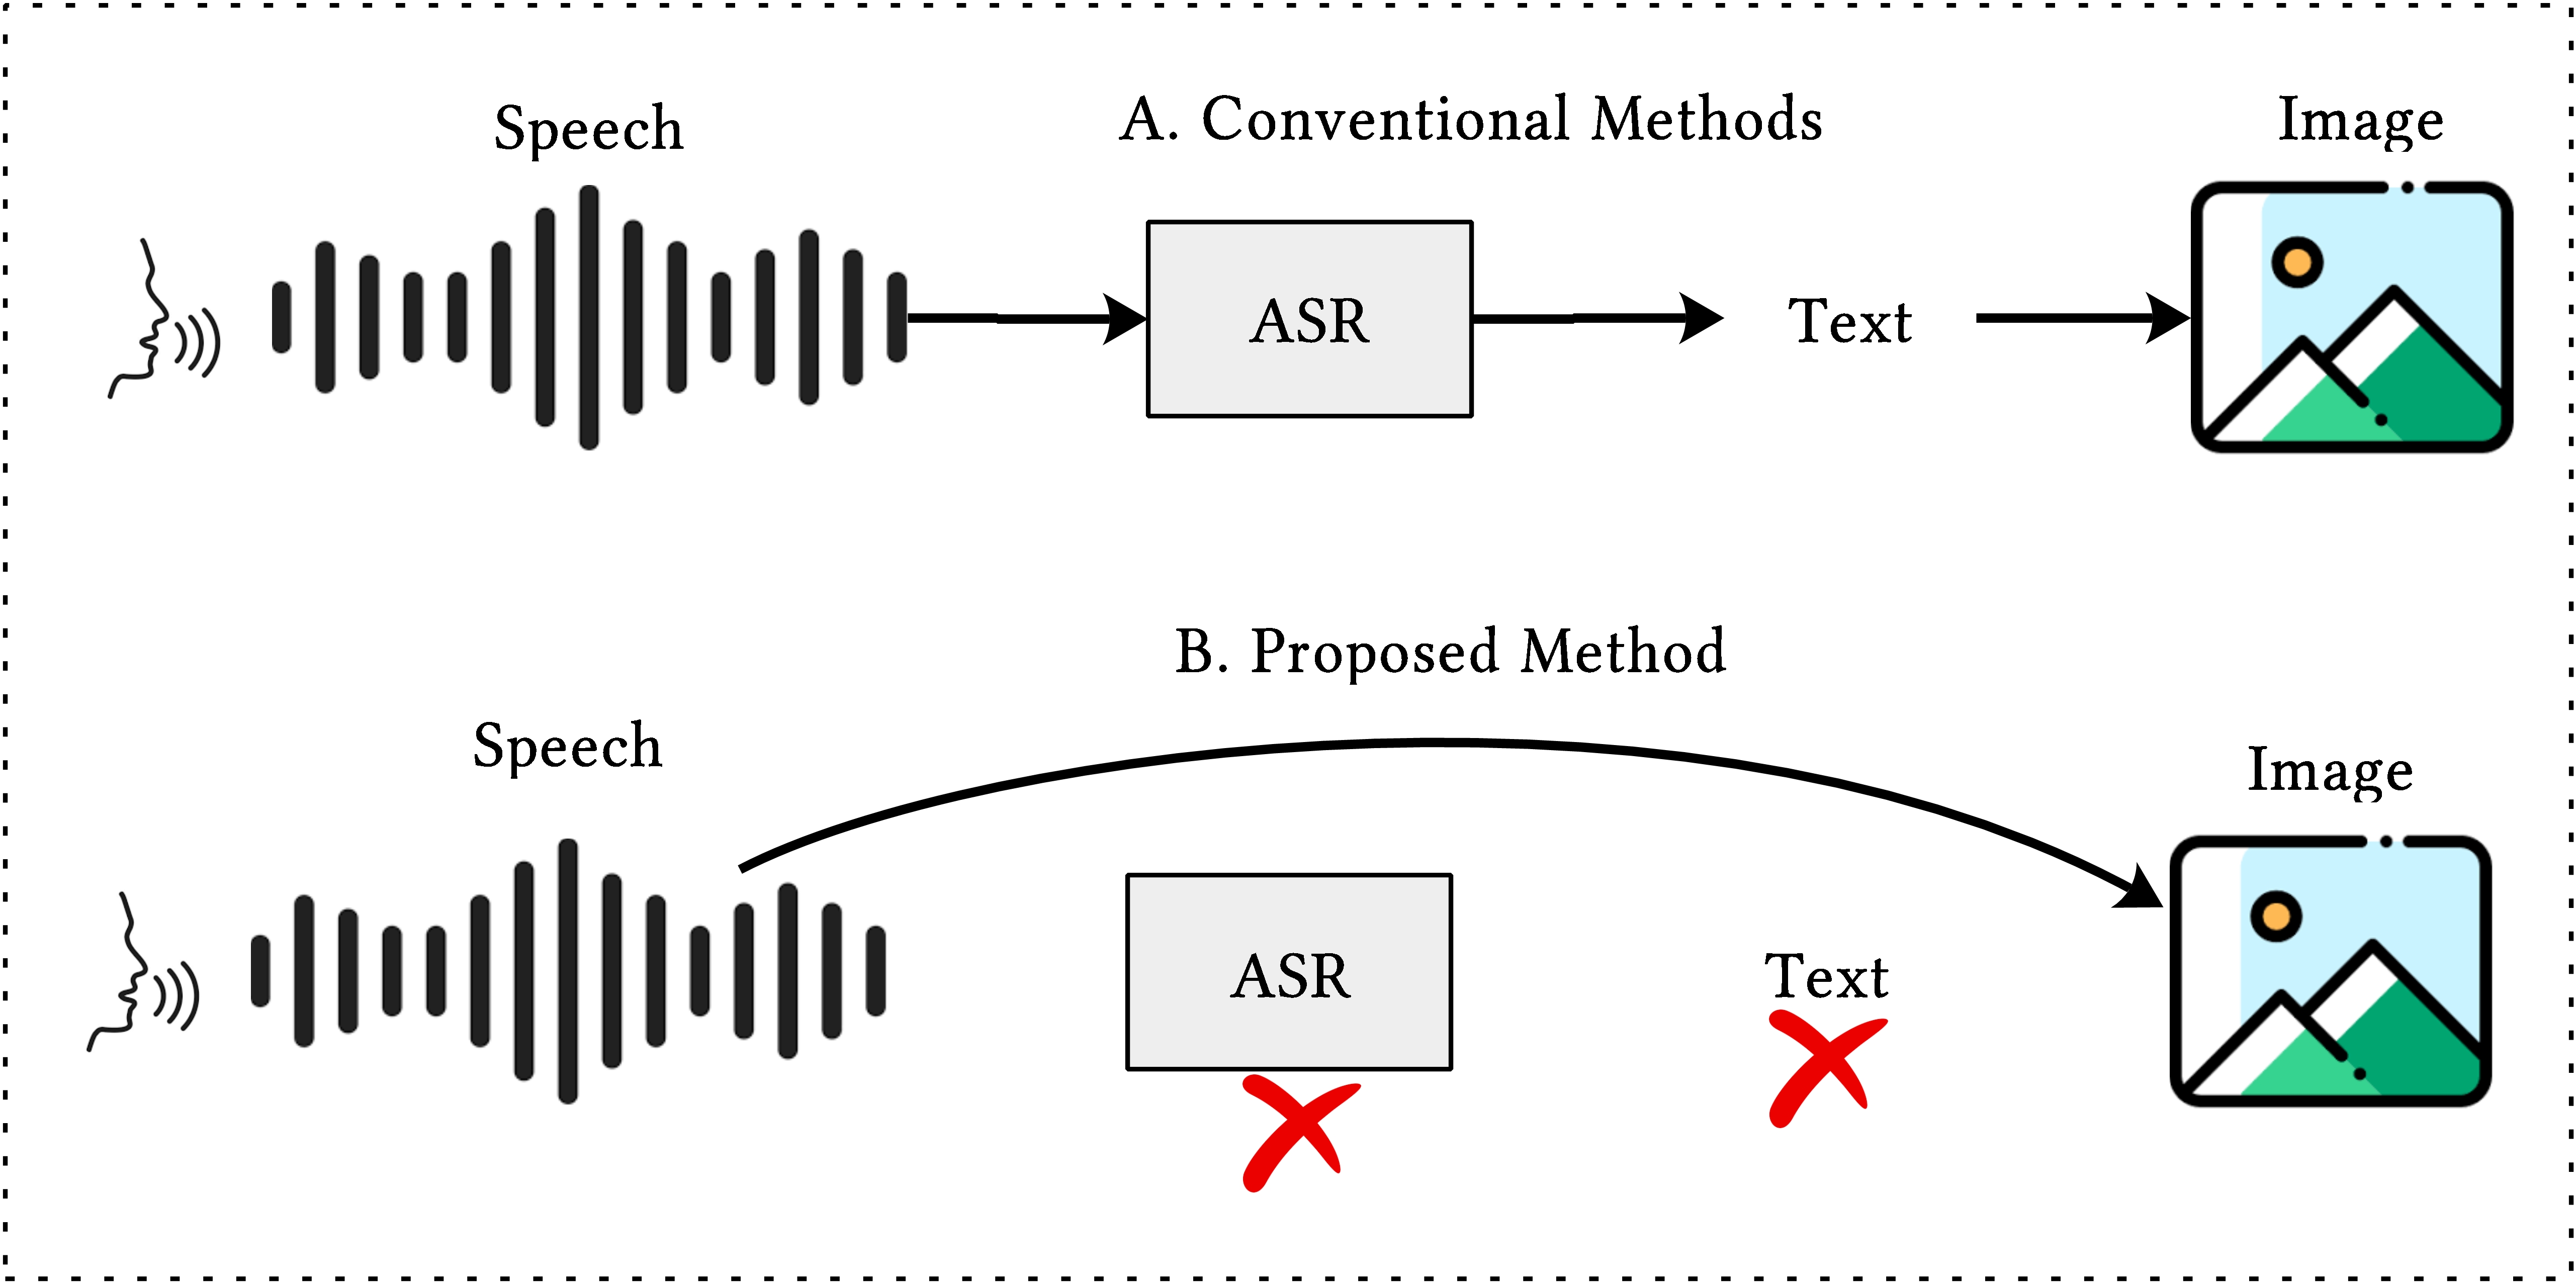
Direct Speech-to-Image Synthesis framework.
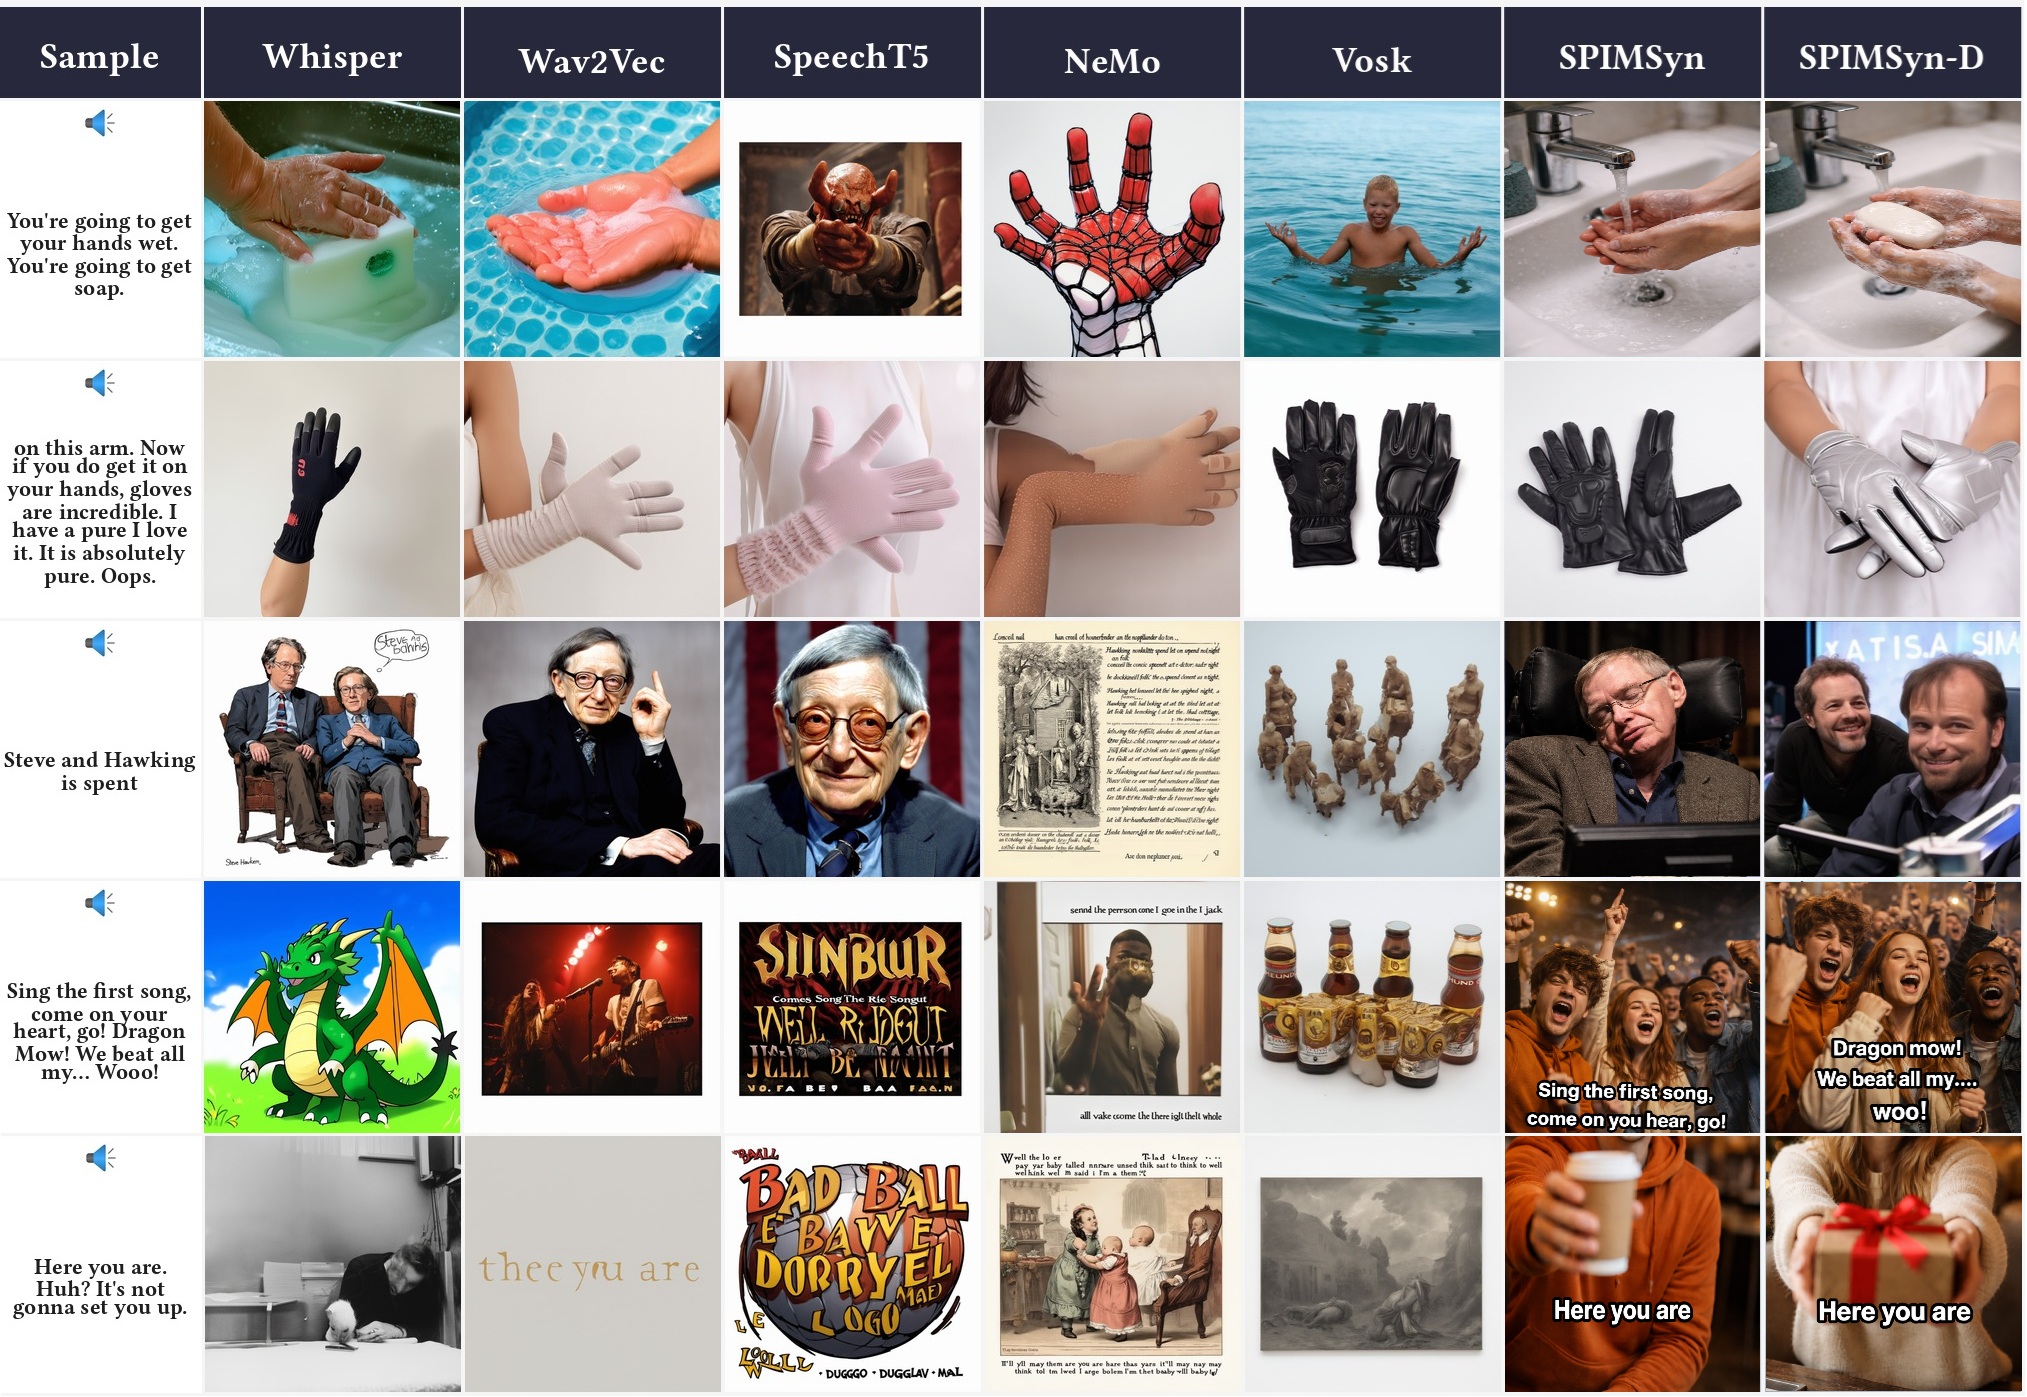
Generating images directly from spoken language without intermediate text transcription remains a fundamental challenge in cross-modal perception. Existing approaches cascade Automatic Speech Recognition (ASR) with Text-to-Image (T2I) models, introducing compounding transcription errors and latency that may degrade image quality. We eliminate this bottleneck by proposing SPIMSyn and SPIMSyn-D, two SPeech to IMage Synthesis frameworks that adapt Stable Diffusion 3.5 for direct Speech-to-Image (S2I) generation. A novel 3-Branch Transformer Decoder predicts conditioning embeddings corresponding to the three text encoders of Stable Diffusion 3.5: CLIP-L, CLIP-G, and T5-XXL.
To obtain speech representations, SPIMSyn employs a pretrained Whisper Encoder, while SPIMSyn-D uses training-free discrete mel-filterbank tokenization through dMel. Extensive experiments demonstrate that both SPIMSyn and SPIMSyn-D eliminate explicit ASR decoding, thereby reducing cascading errors, improving image generation fidelity, and achieving lower end-to-end latency compared with conventional cascaded Speech-to-Image pipelines.
Overview of the proposed SPIMSyn and SPIMSyn-D frameworks for direct speech-to-image synthesis.
We evaluate our proposed SPIMSyn and SPIMSyn-D on synthesized and real-world speech datasets to demonstrate direct speech-to-image generation without intermediate ASR transcription.
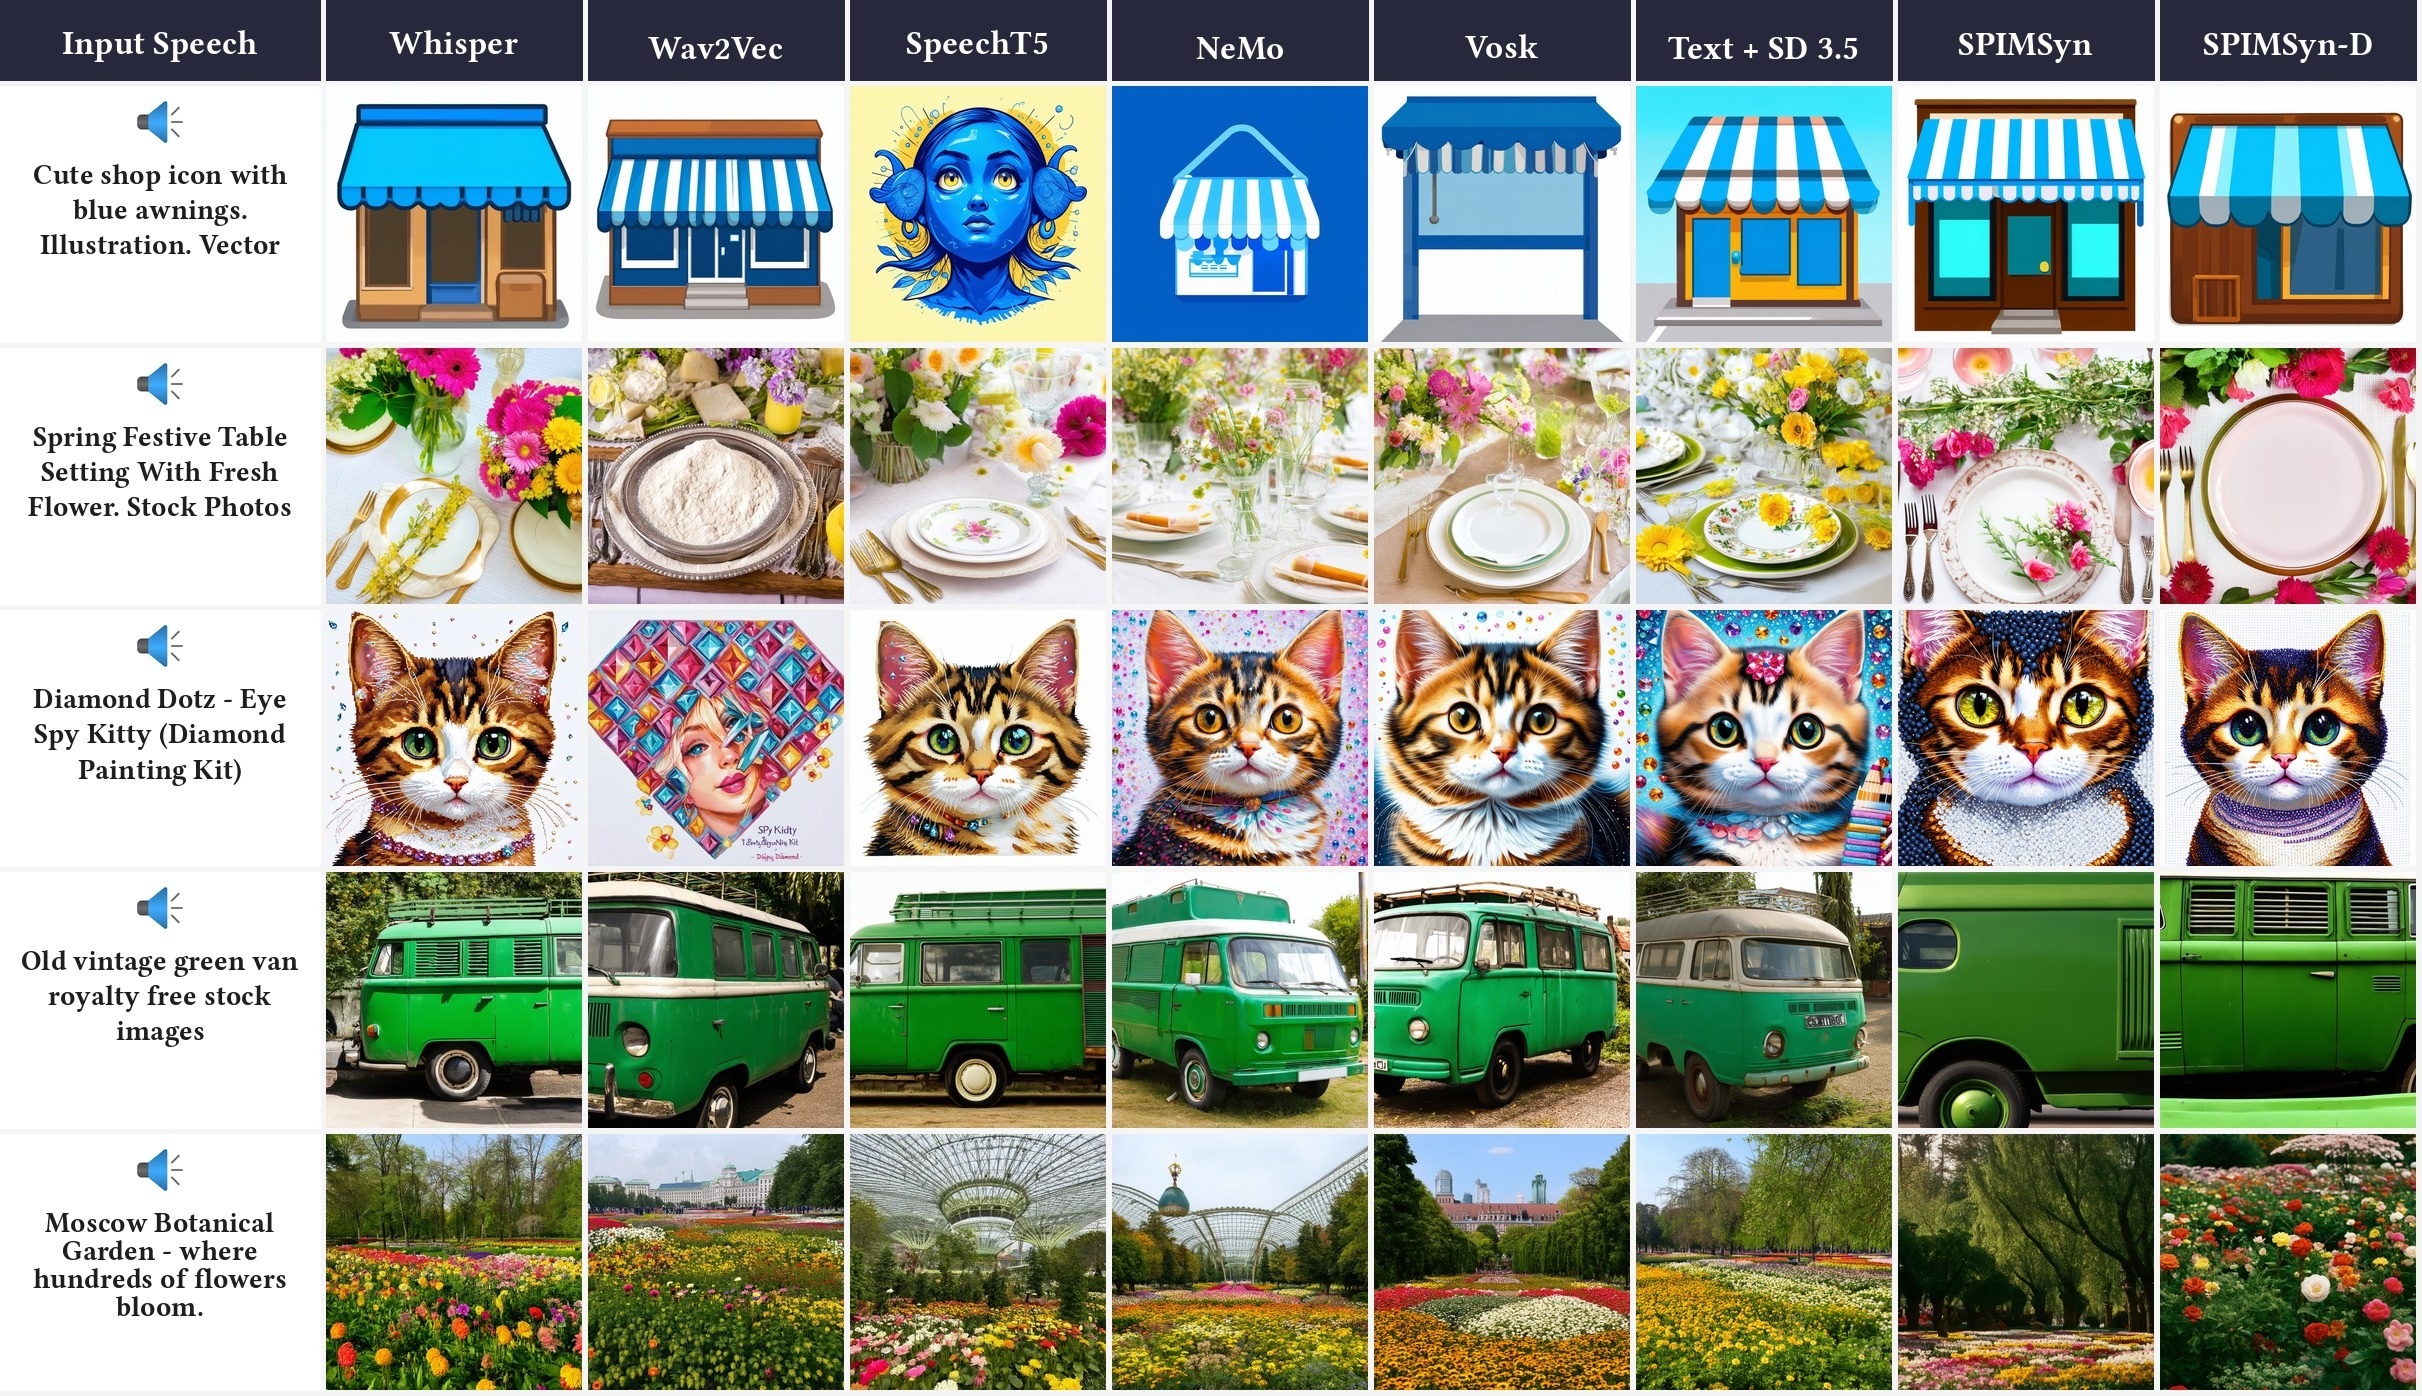
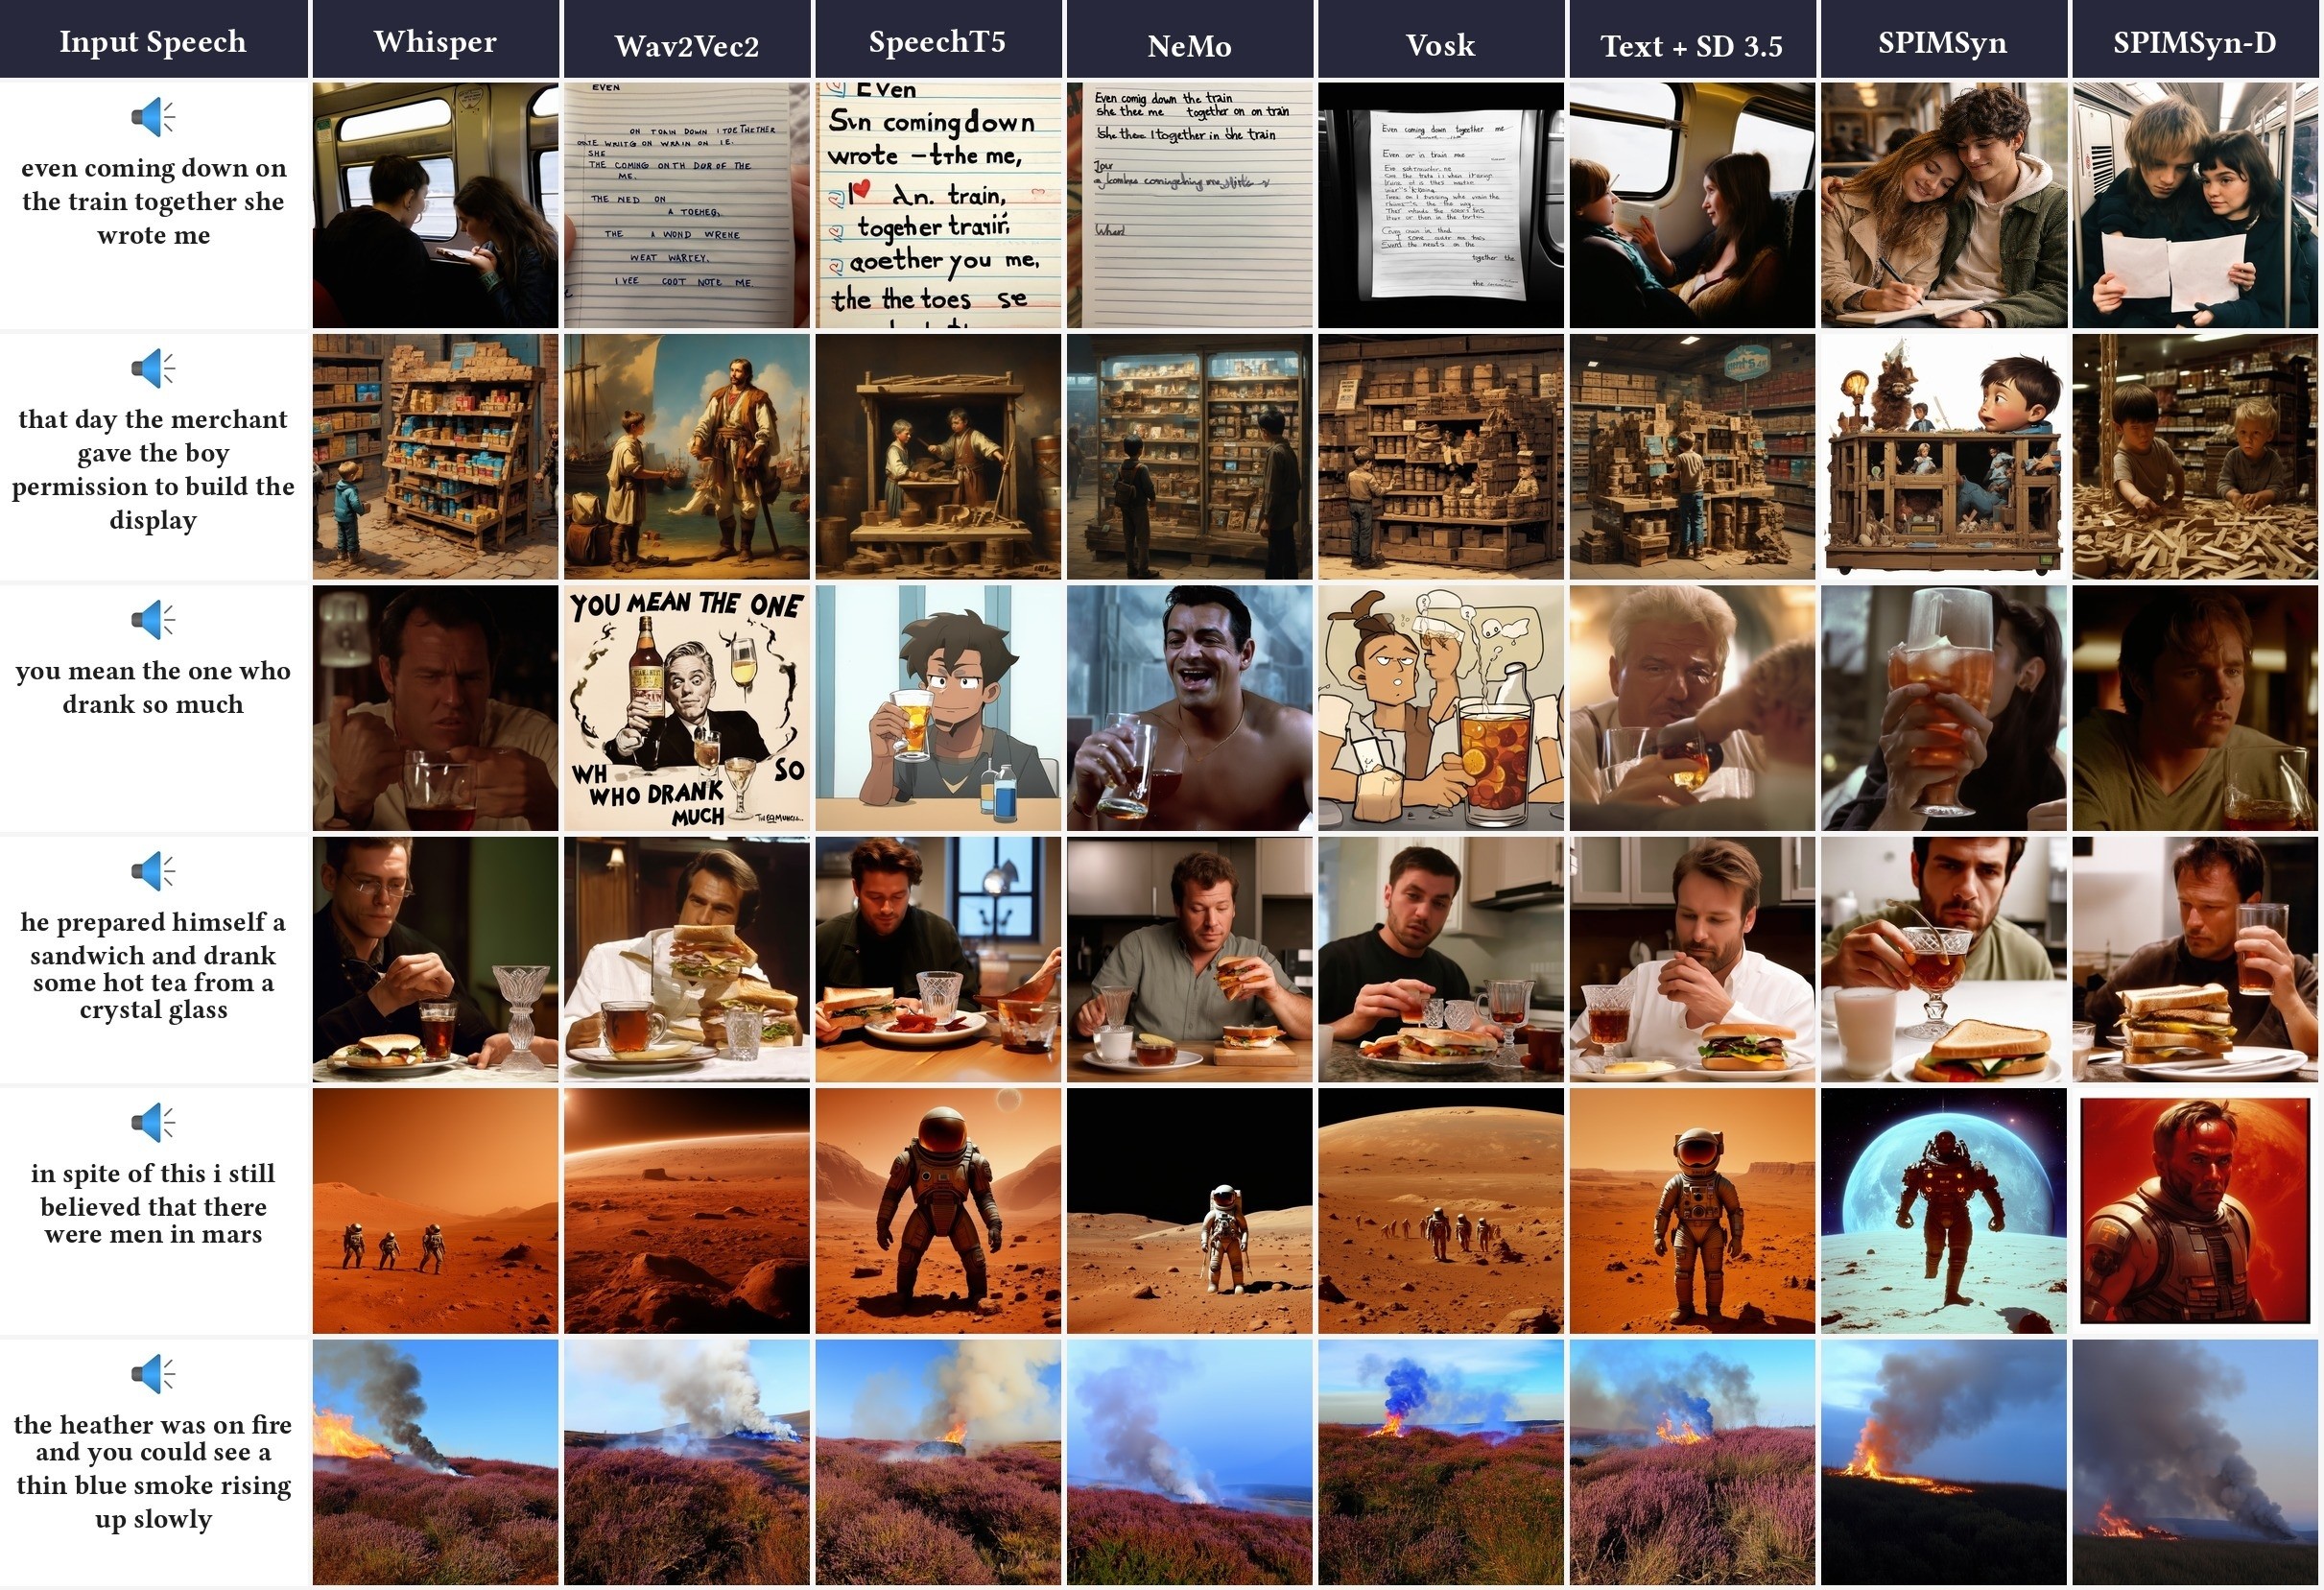
We first evaluate our framework on a synthesized speech version of the LAION-5B dataset. Compared with cascaded Speech-to-Image baselines, SPIMSyn and SPIMSyn-D generate images that more faithfully preserve the semantic content of the spoken input while avoiding transcription errors introduced by Automatic Speech Recognition (ASR).
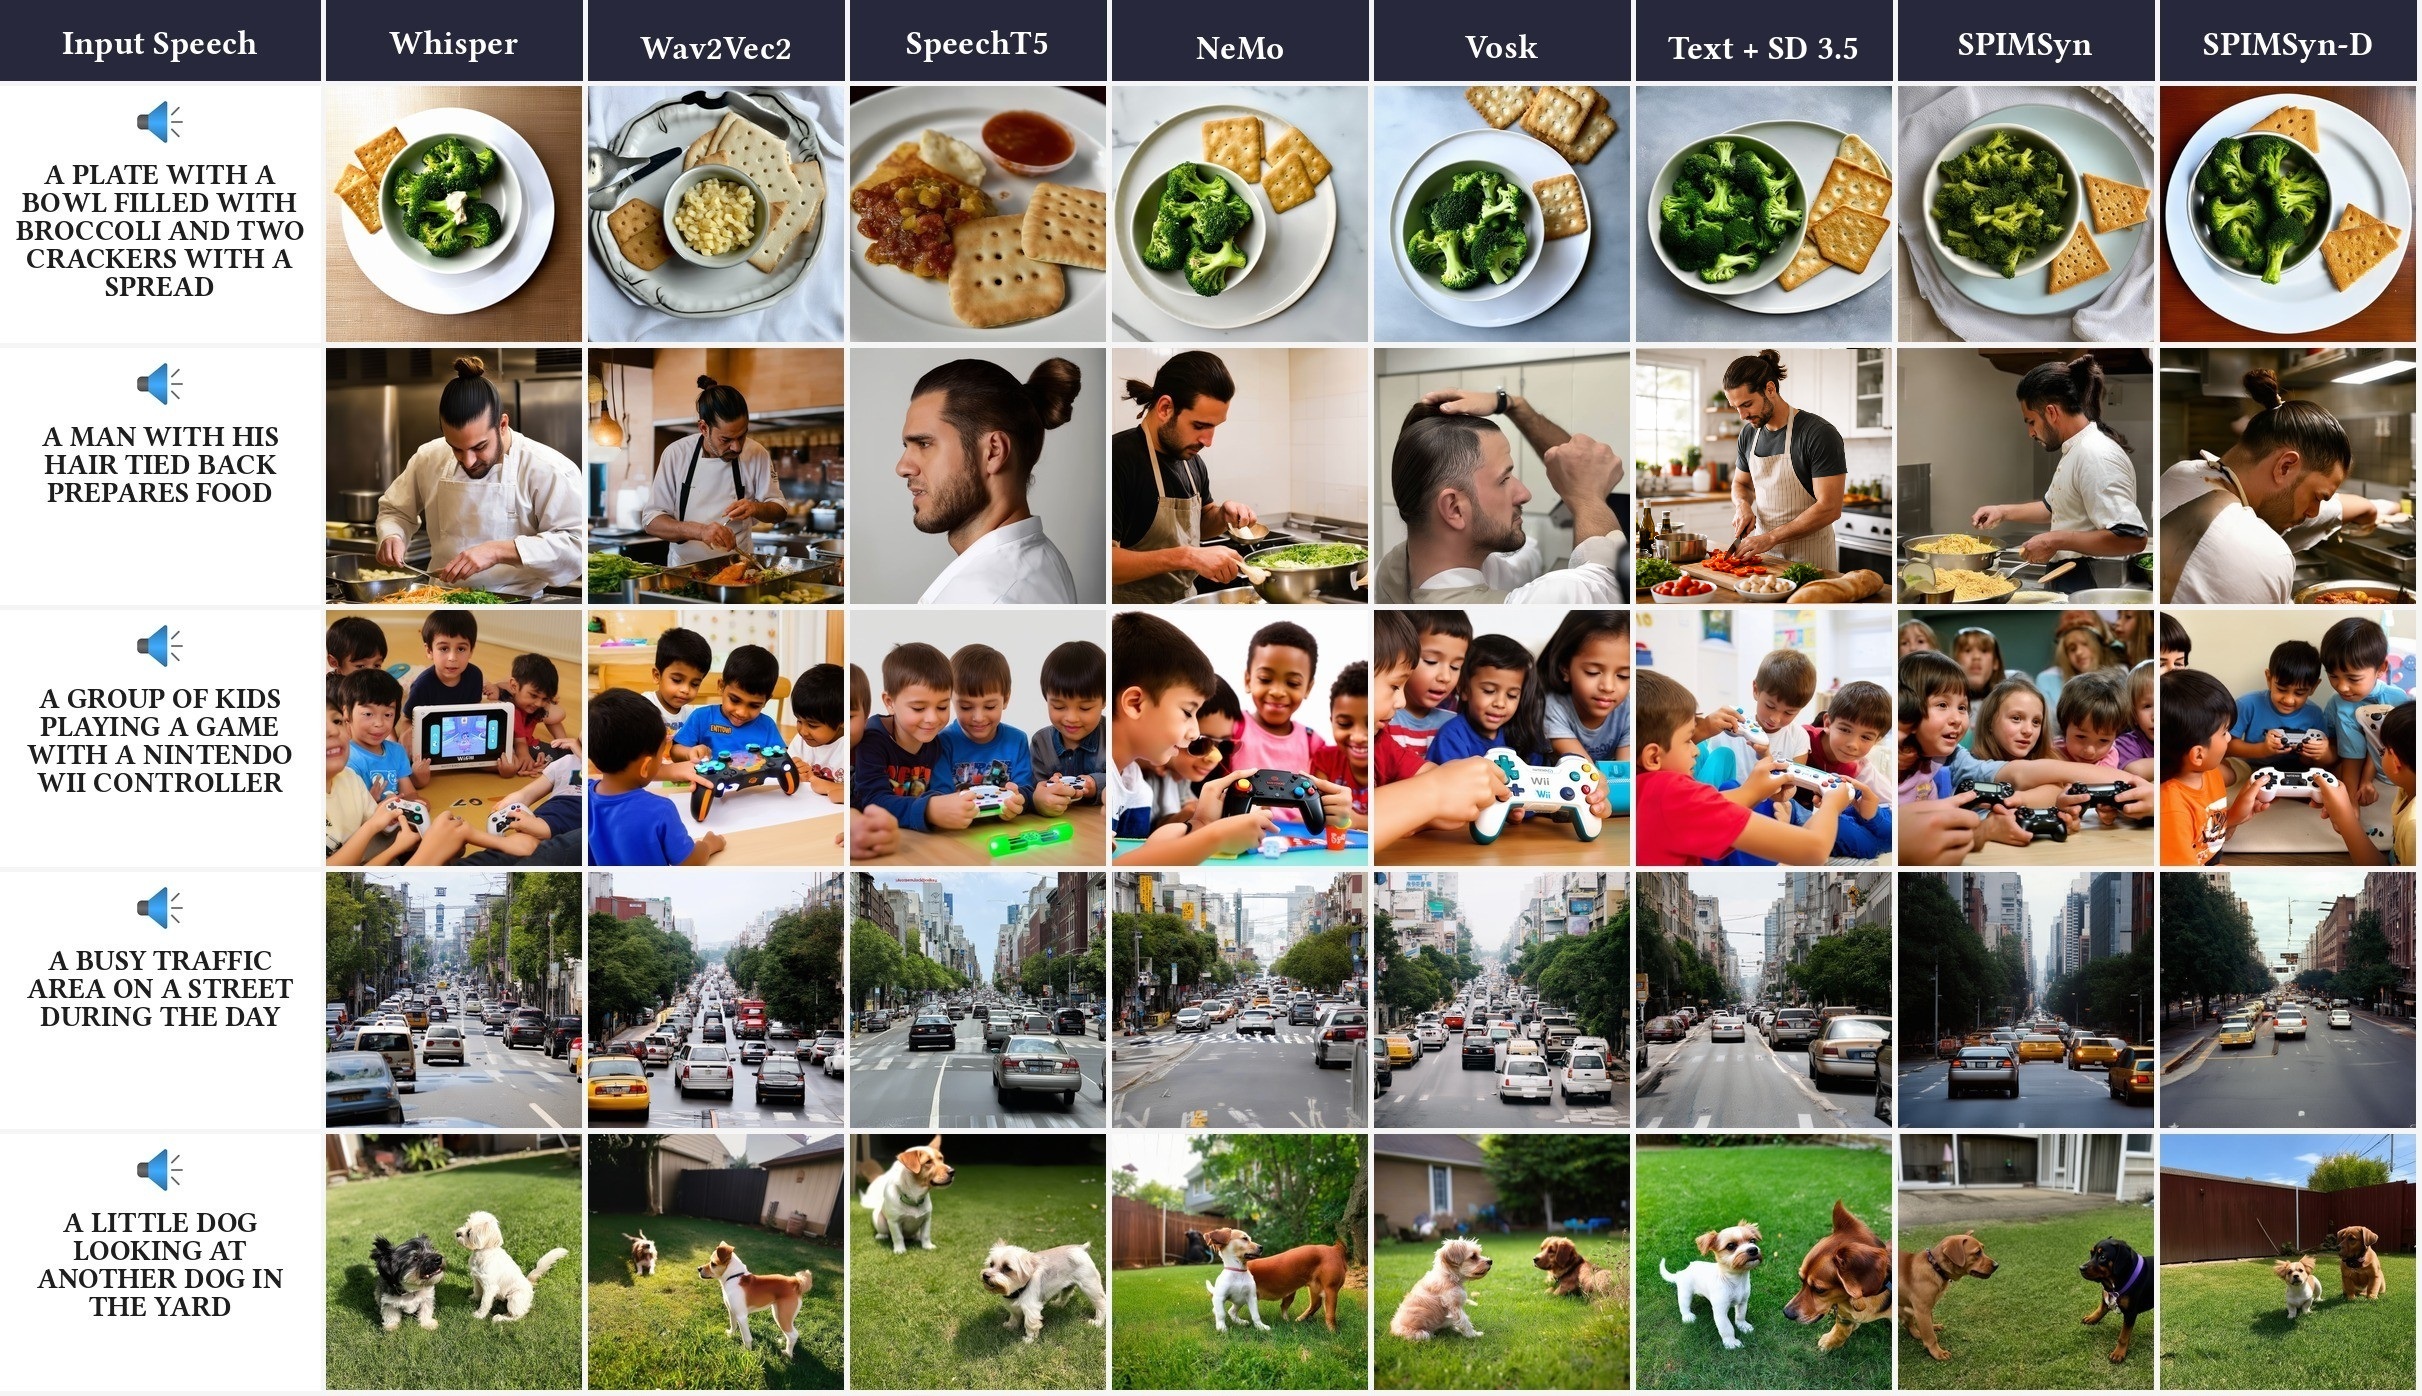
We further evaluate the proposed framework on the Spoken COCO dataset containing natural human speech. Although trained on synthesized speech, SPIMSyn and SPIMSyn-D generalize effectively to real spoken descriptions without additional fine-tuning.
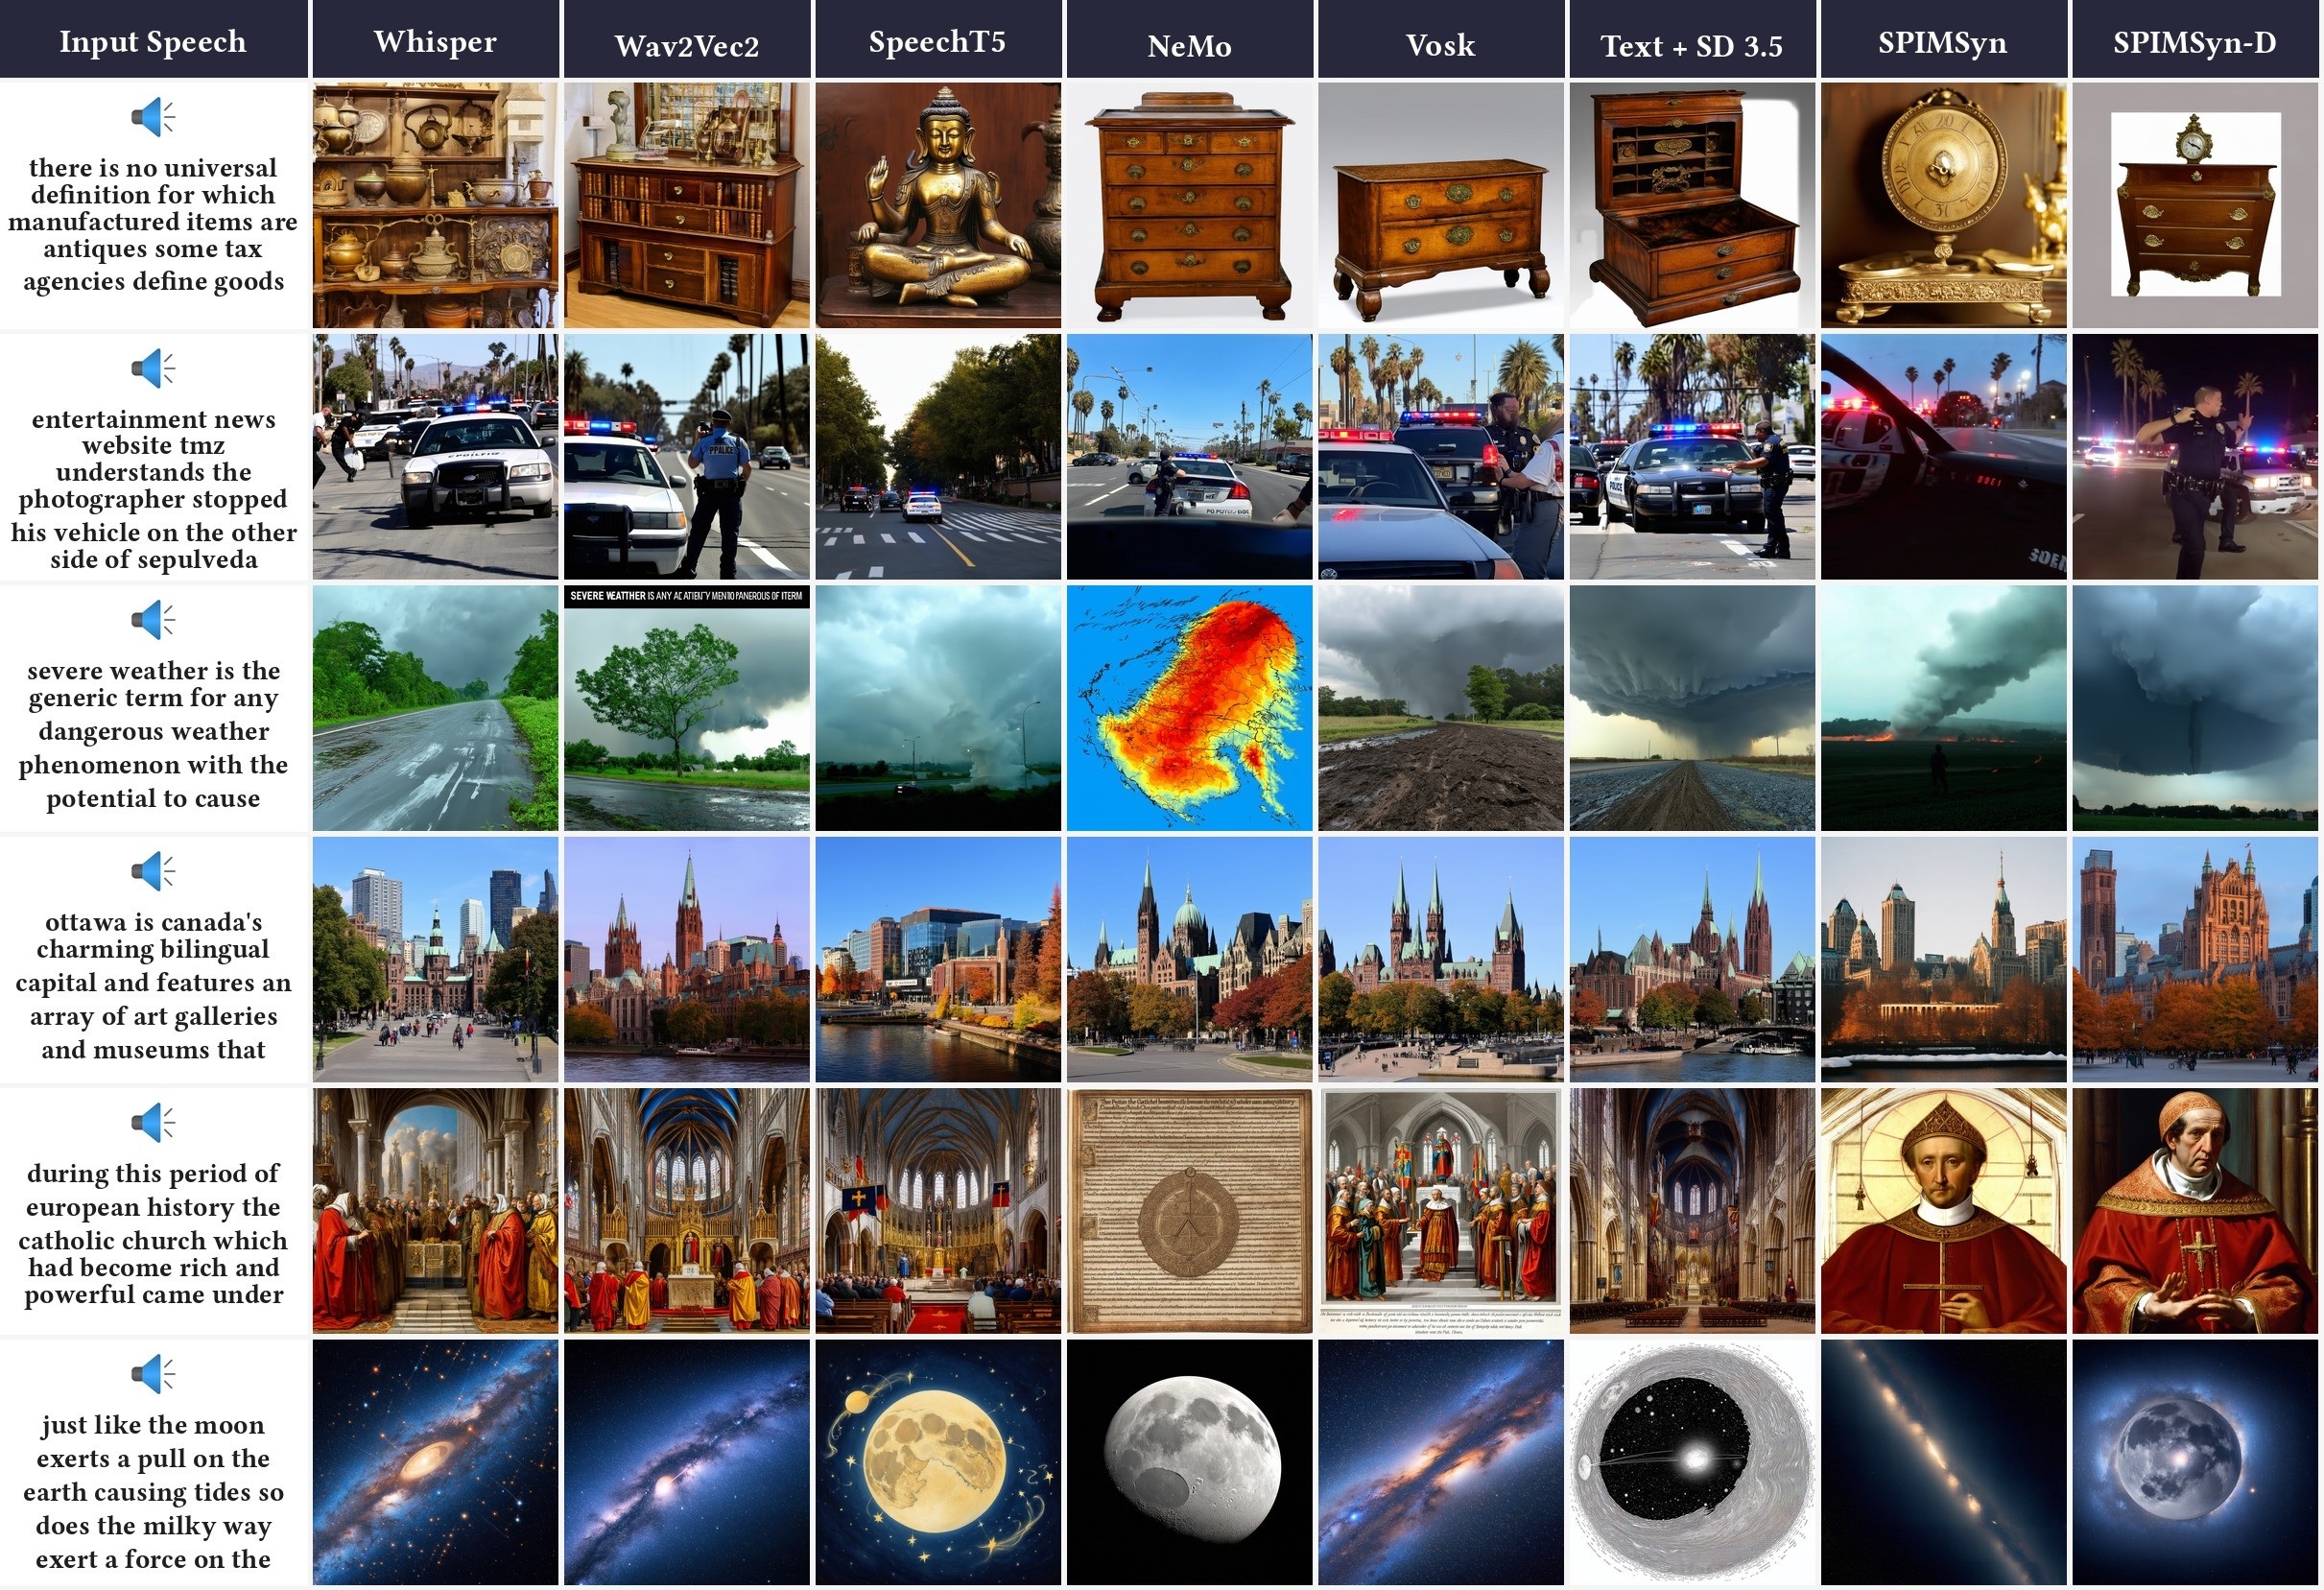
To evaluate robustness on long and complex spoken descriptions, we conduct experiments on FLEURS benchmark. SPIMSyn and SPIMSyn-D accurately capture semantic information even for lengthy speech inputs.
We evaluate our approach on Common Voice dataset containing diverse speakers recorded under different acoustic conditions such as speech in board room meetings and in other environments. The proposed framework demonstrates strong robustness across speaker variability while maintaining semantic fidelity.
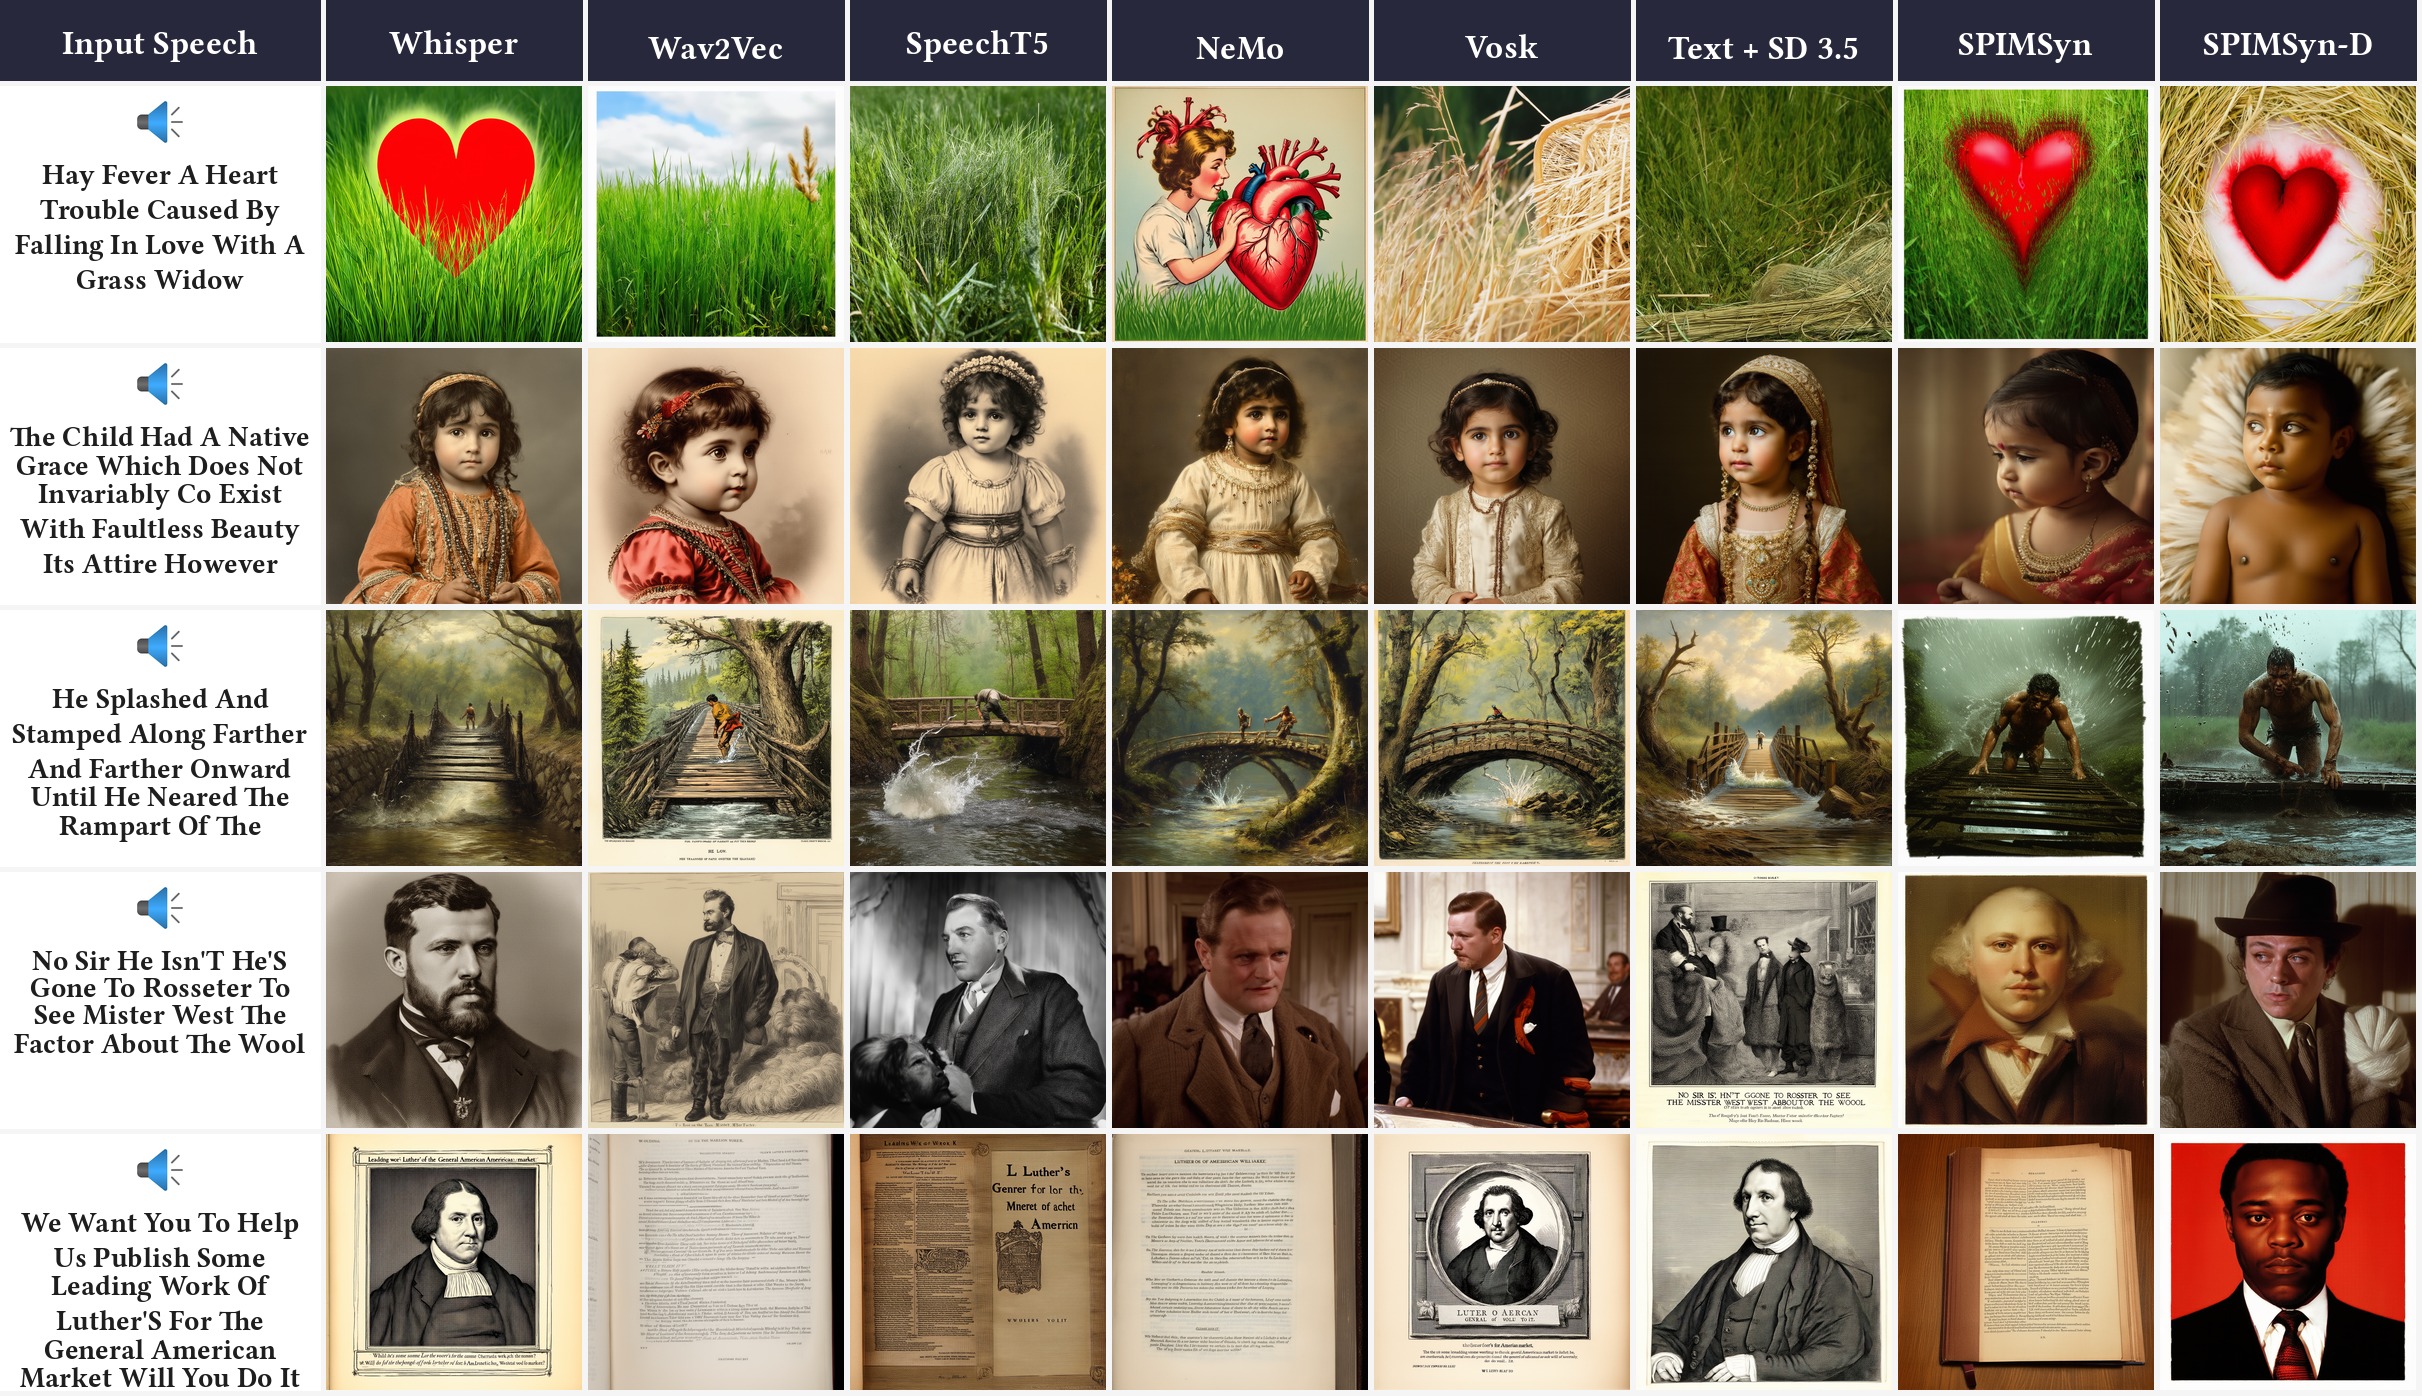
To evaluate robustness on unconstrained spoken language, we conduct experiments on the LibriSpeech benchmark. The proposed SPIMSyn and SPIMSyn-D frameworks generate meaningful images directly from long-form speech without relying on intermediate Automatic Speech Recognition. These results demonstrate strong generalization beyond the synthesized training corpus.
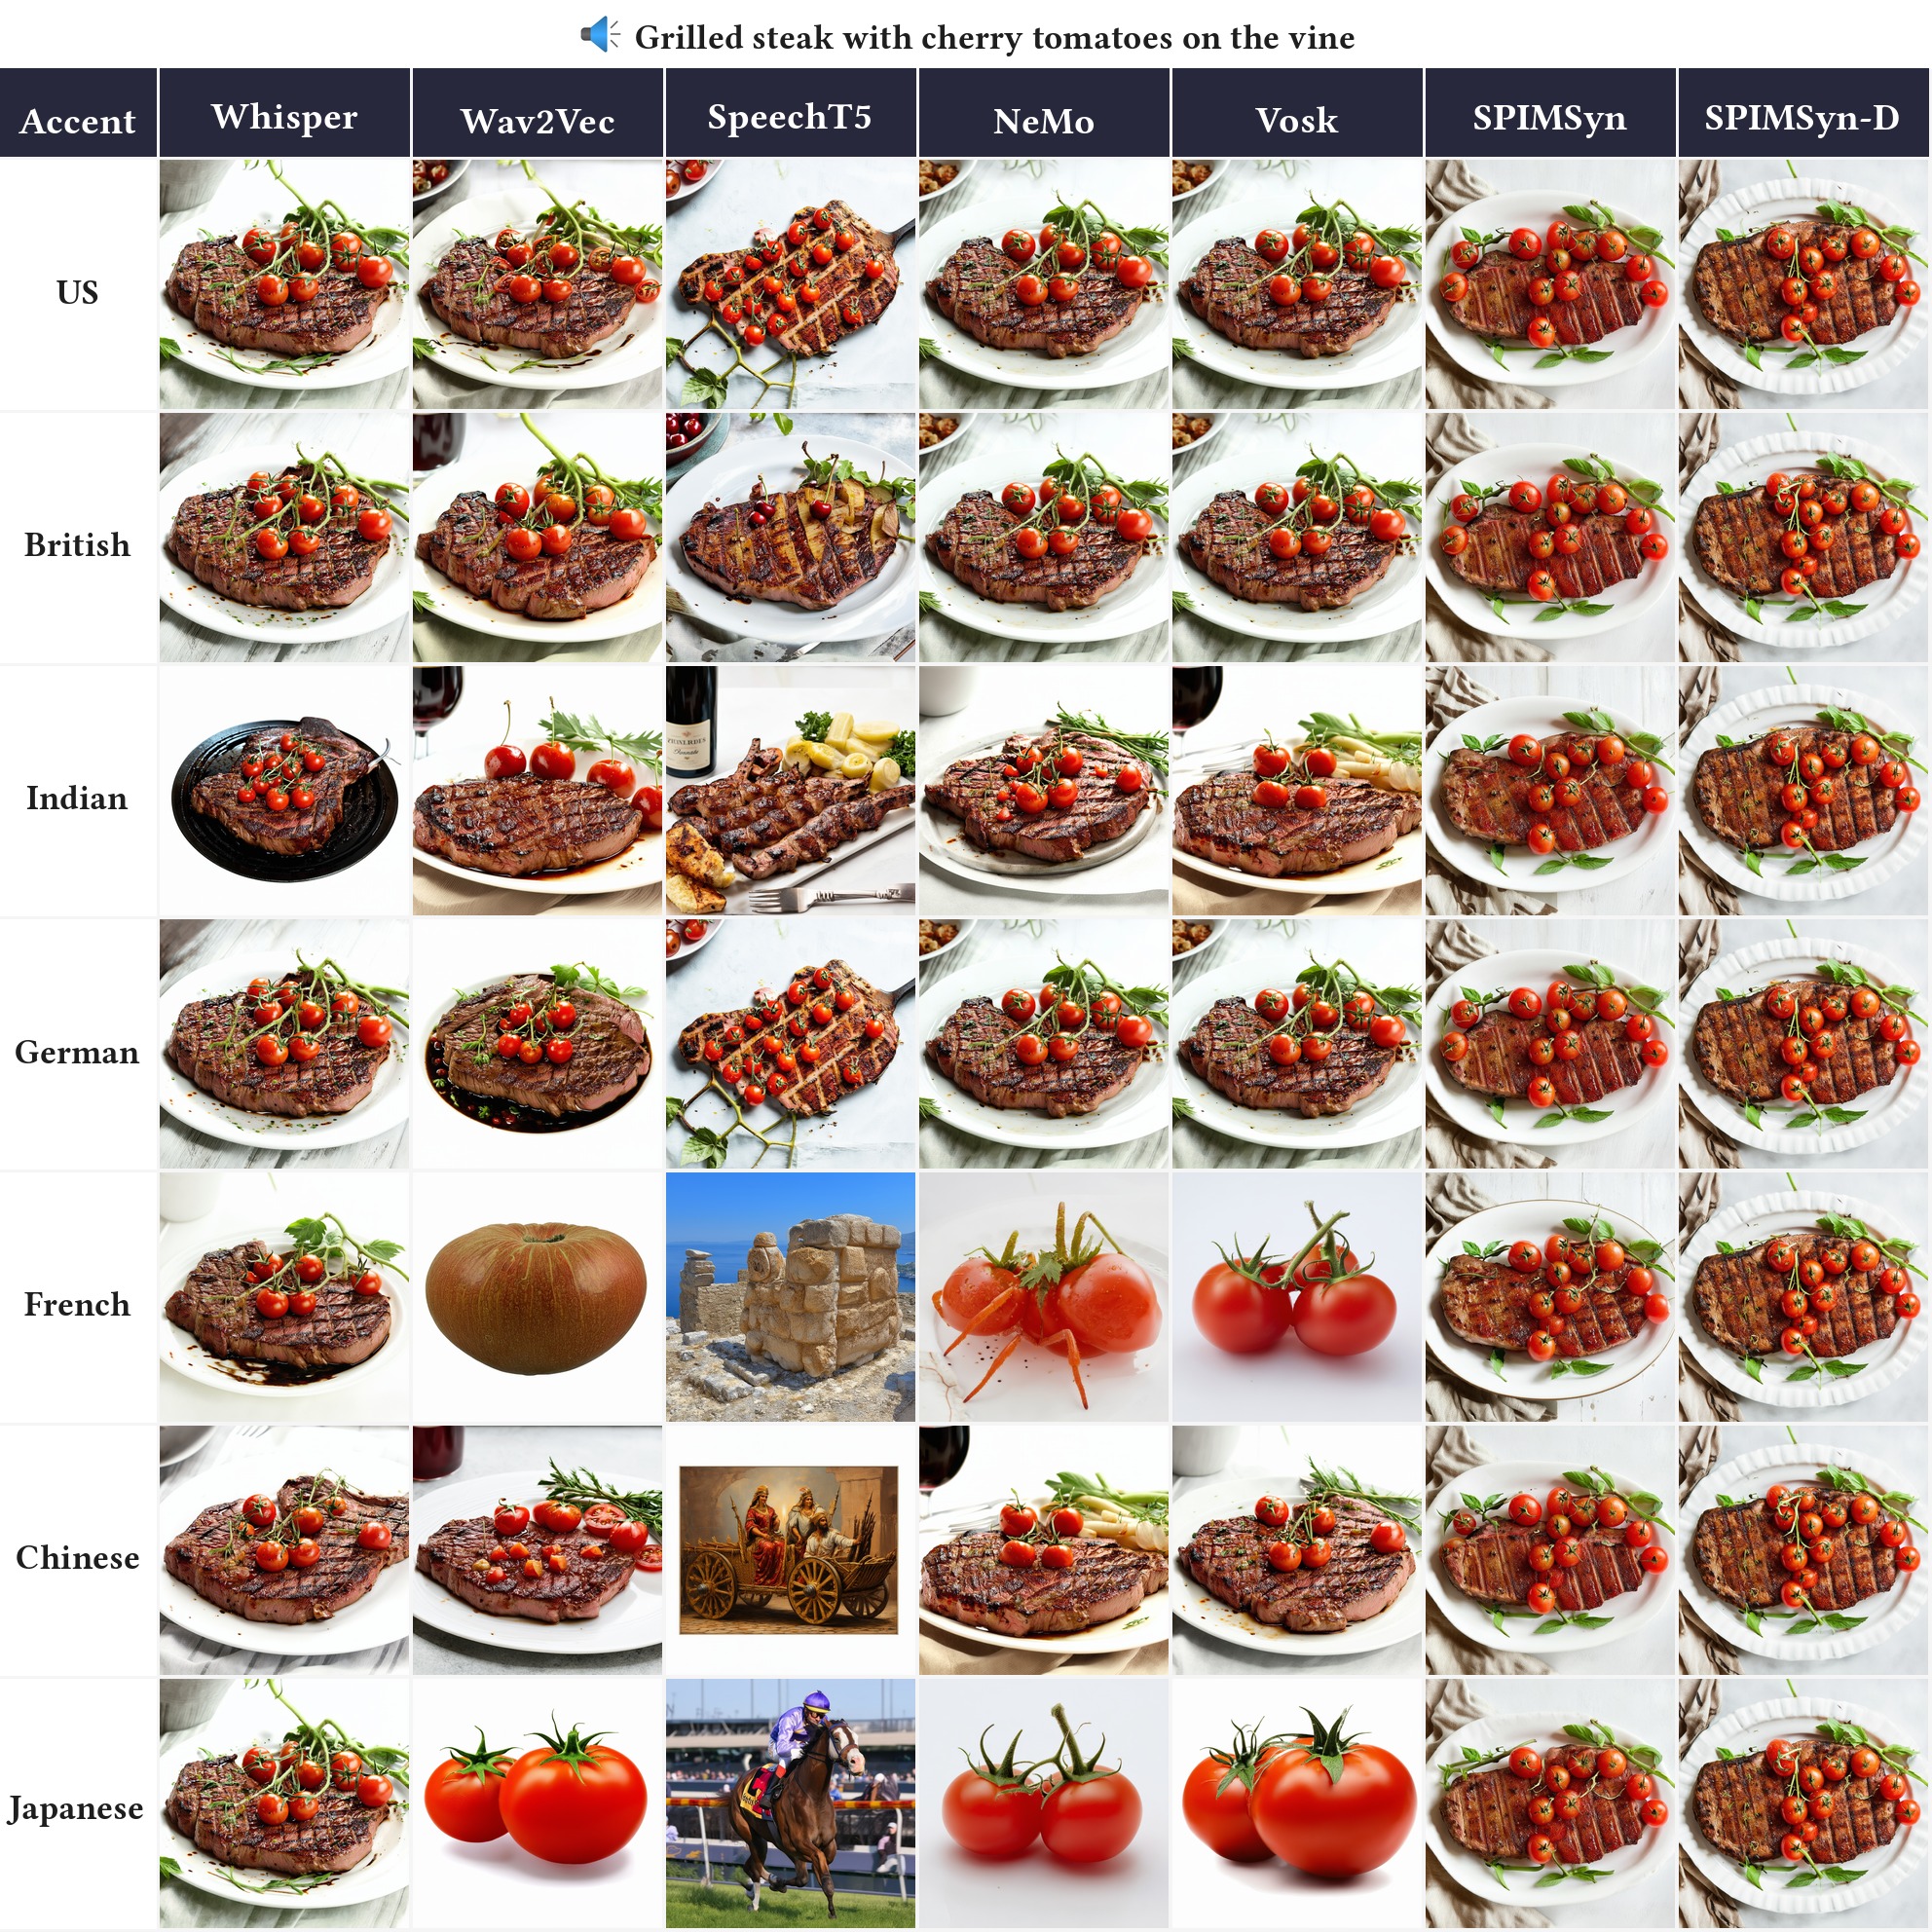
We evaluate the proposed framework across multiple English accents including American, British, Indian, German, French, Chinese, and Japanese speakers. SPIMSyn and SPIMSyn-D consistently generate meaningful images irrespective to accent variations.
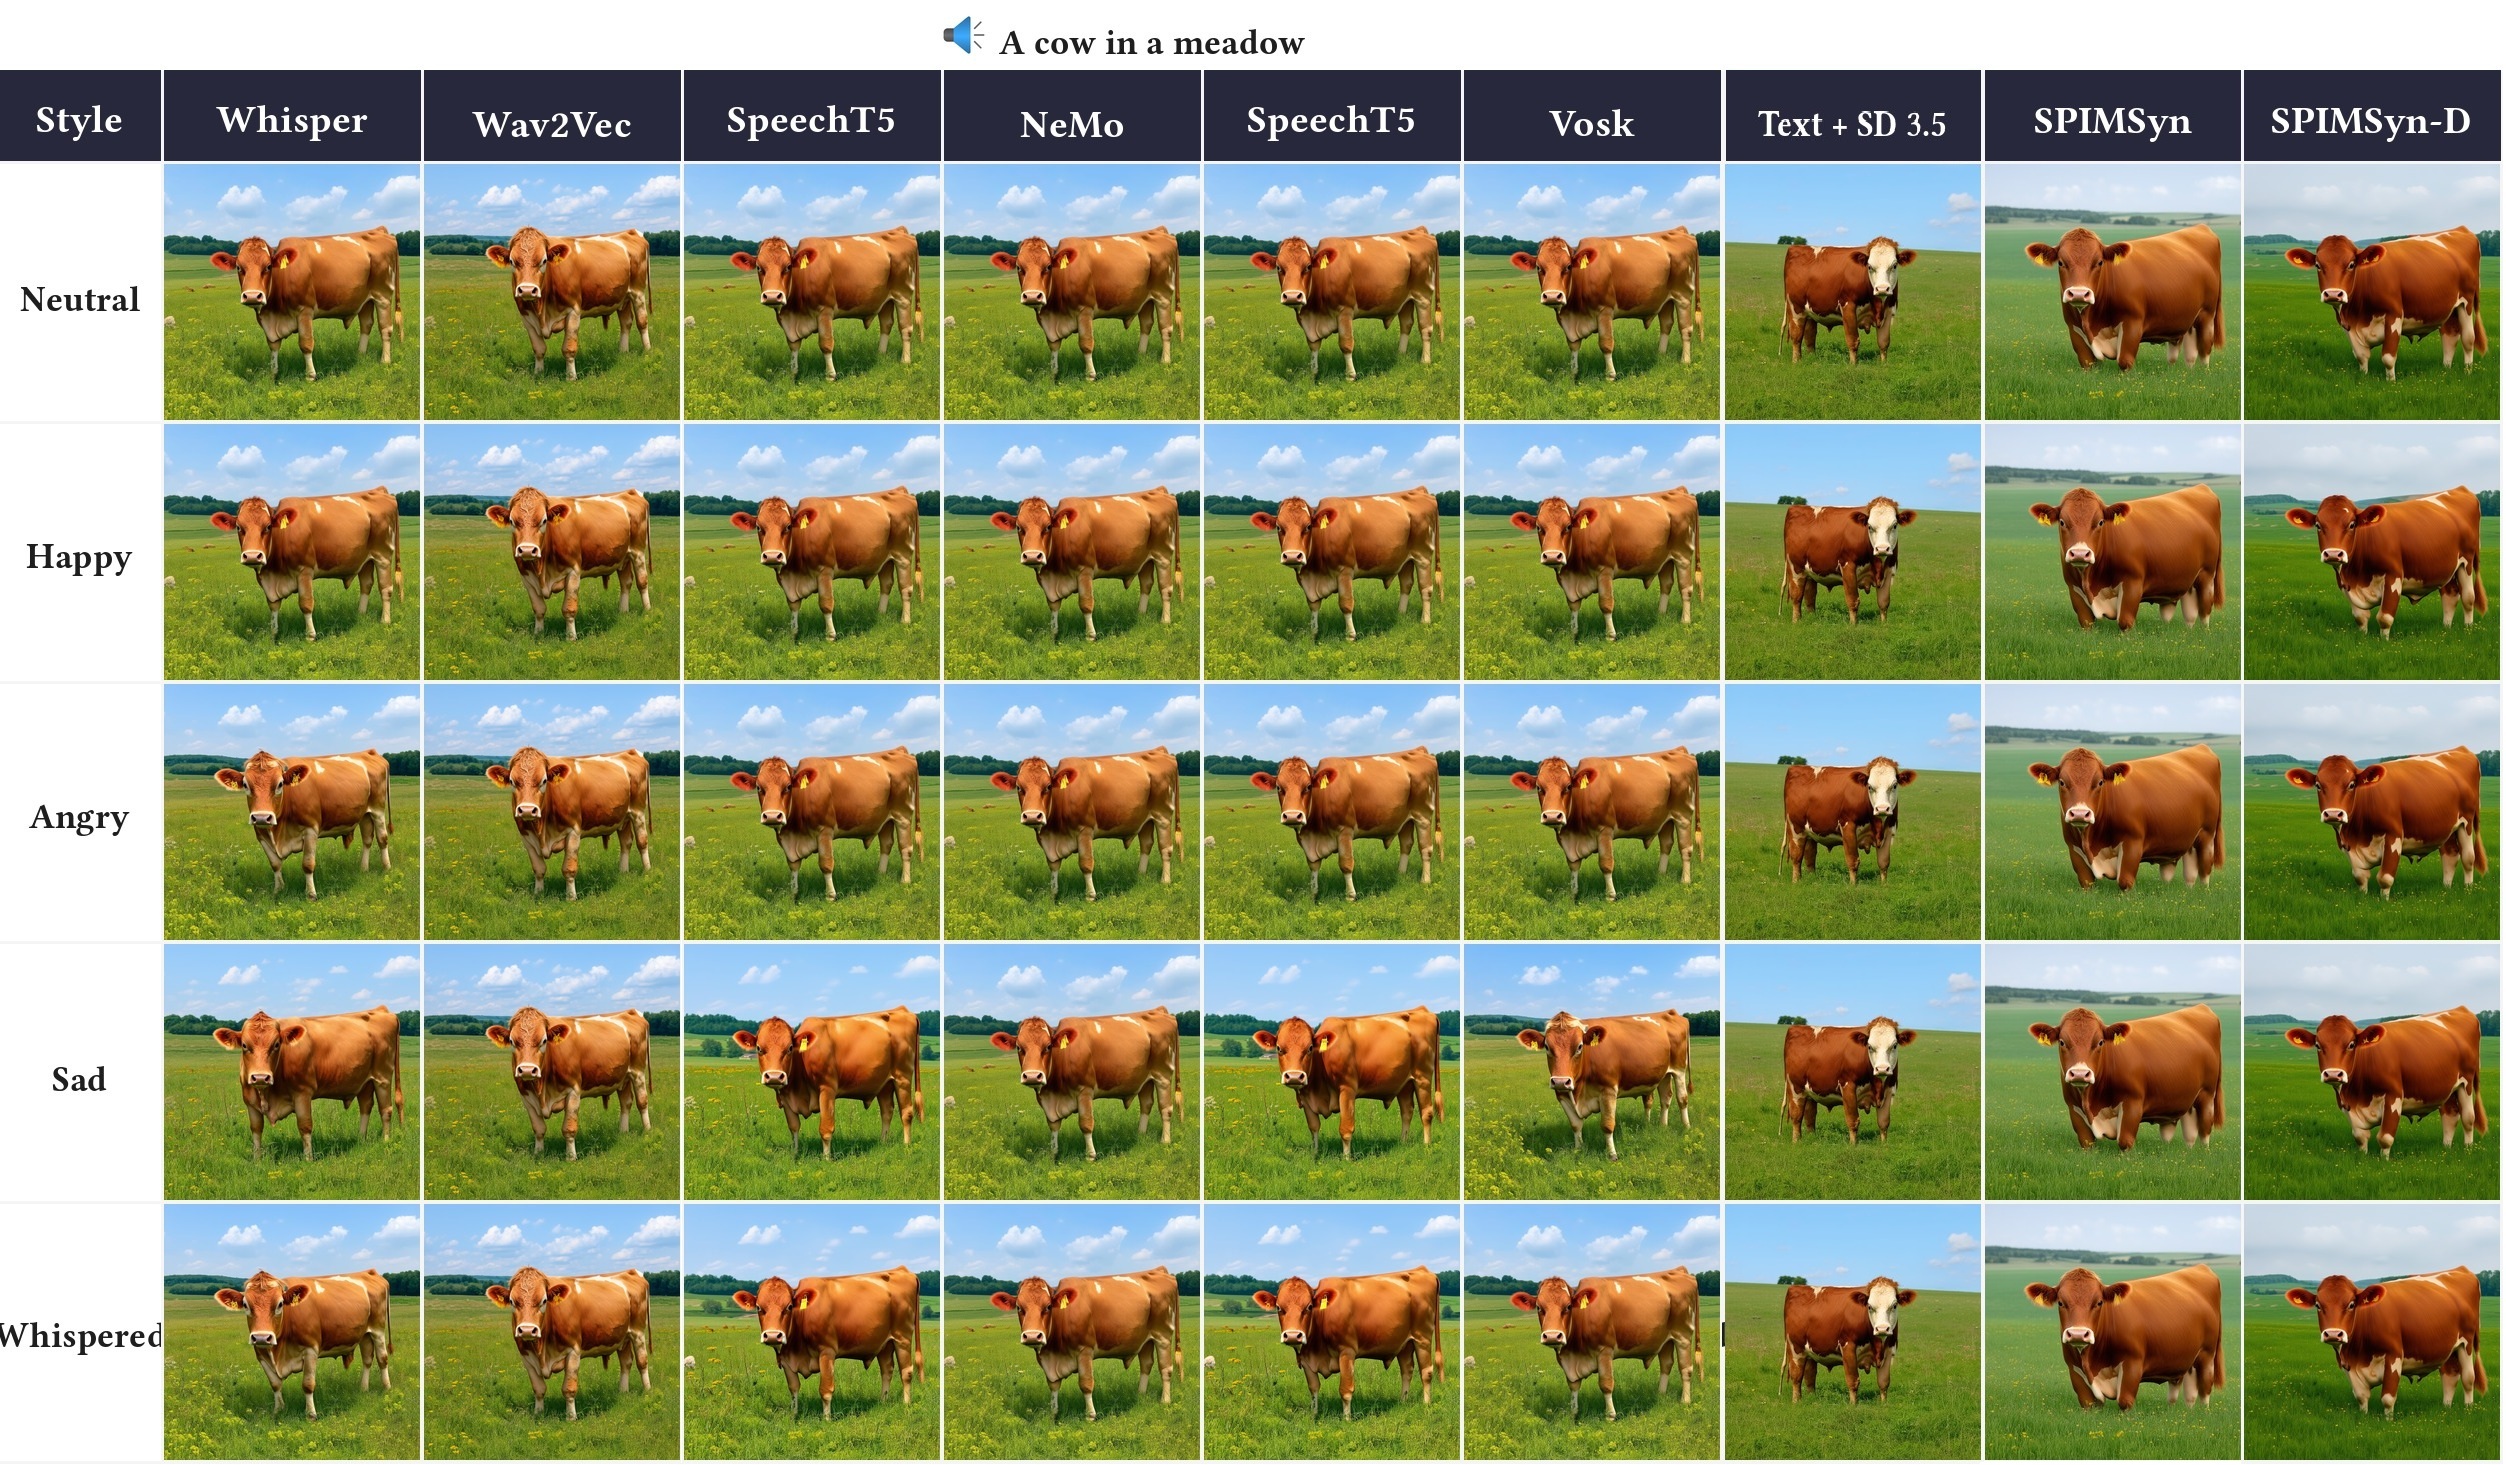
We investigate whether variations in speaking style, including neutral, happy, angry, sad, and whispered speech, influence the generated images.
Beyond spoken words, human speech often contains paralinguistic cues such as laughter, sighs, and non-verbal vocalizations. We evaluate whether these signals influence the generated images. The proposed framework demonstrates robustness to such acoustic variations of the spoken content.
Although our framework is trained for direct Speech-to-Image generation, the predicted multimodal conditioning embeddings can also be integrated into modern diffusion-based video generation models. The following examples demonstrate preliminary results, illustrating the potential of extending toward direct Speech-to-Video synthesis.
@article{coming soon}